- analytics
- Startup Tools & AI SaaS
IdeaValidator: how the five-dimension scoring engine works
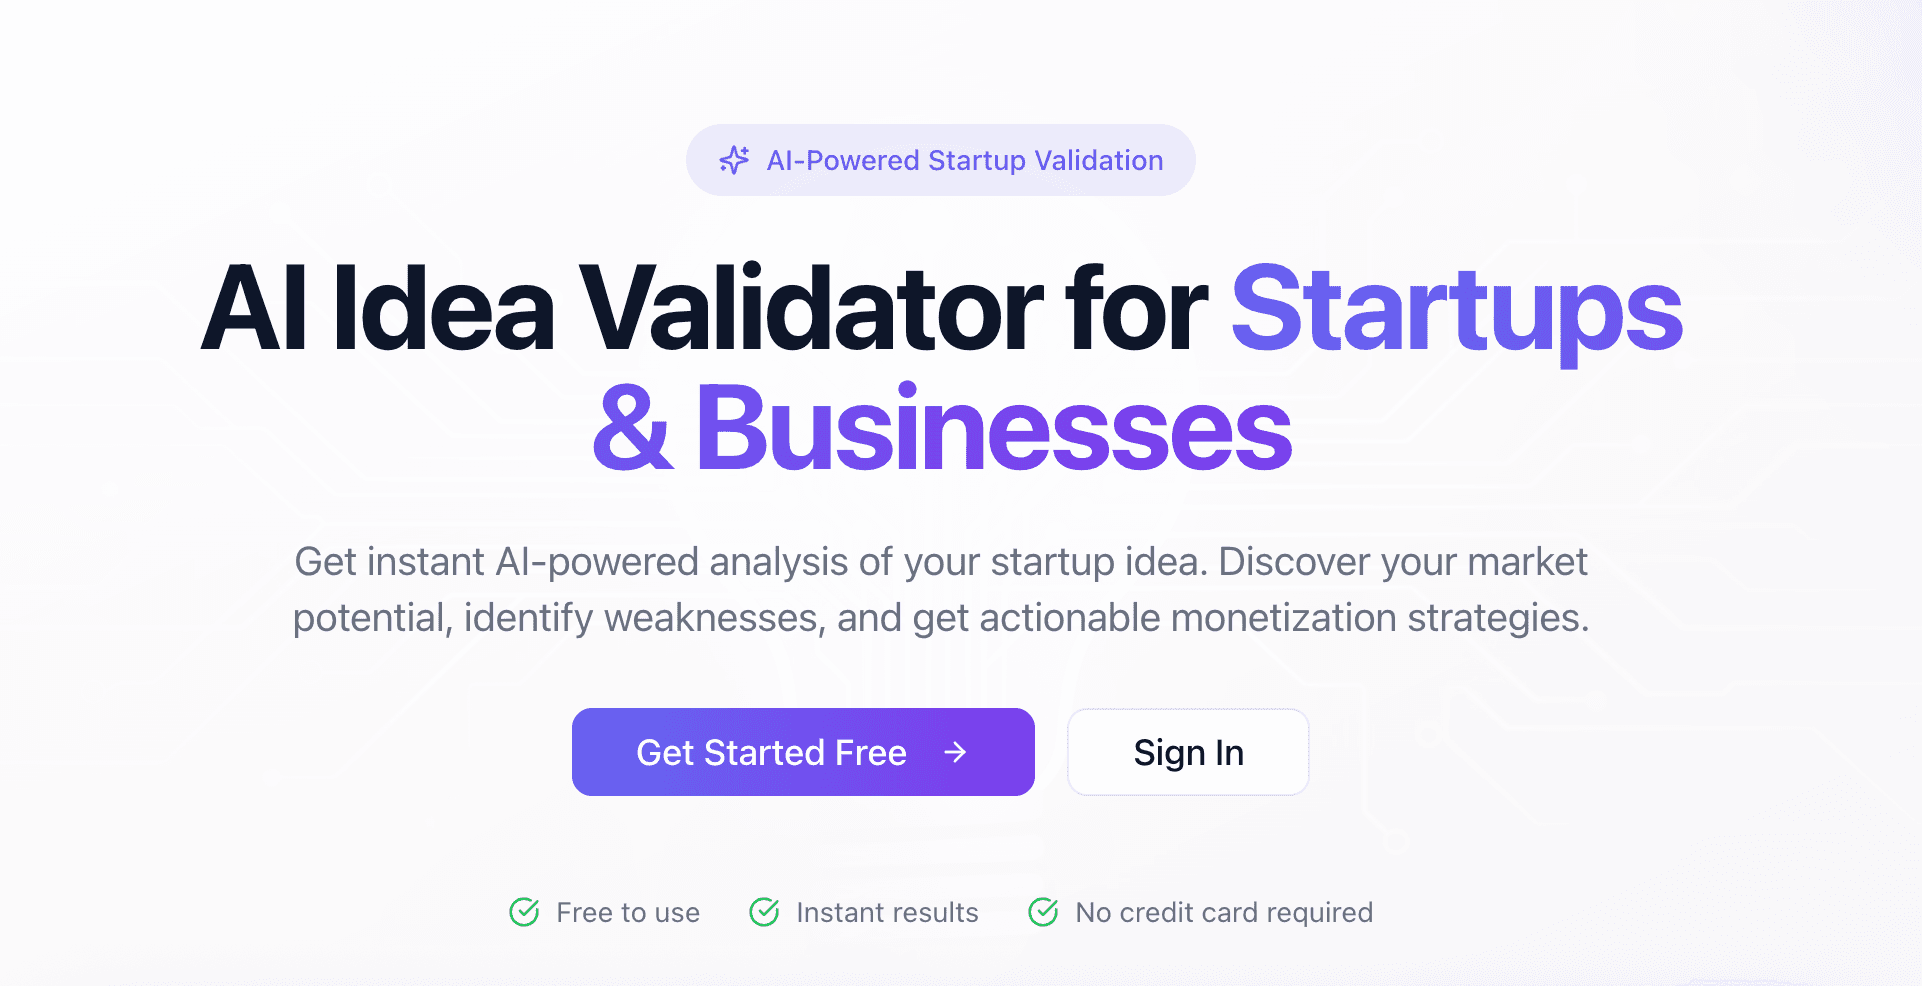
An idea typed in plain language comes back scored 0–100 on five weighted criteria, each graded on its own, with revenue models attached to the result.
- AI & Machine Learning
- Full-Stack Development
- Product Engineering
At a glance
- Sector
- Startup Tools & AI SaaS
- Type
- analytics
- Services
- AI & Machine Learning · Full-Stack Development · Product Engineering
The problem
What it had to solve
Founders commit months to ideas they have never pressure-tested, because the honest test is awkward to run. Friends and family are biased towards yes, and the questions that decide the thing — is there a market, can it be built, where does the money come from — stay unanswered until changing course is expensive.
The cheapest moment to test an idea is before the first line of code. That put two requirements in tension: low enough friction that a founder actually tries it on a whim, and rigorous enough that the answer is worth carrying into a go or no-go decision.
What we built
How it works
The product is three steps around a language model. A founder types the idea as prose, the model grades it against five weighted criteria, and the app renders each dimension's 0–100 score separately alongside revenue options, each carrying its pros, its cons and an effectiveness rating.
The design decision that matters is refusing to combine the scores. A single number would be easier to render and much less useful: it tells a founder their idea is a 61 without telling them which part is dragging. Grading the five dimensions separately turns a verdict into an argument the founder can have — and usually the disagreement is with one dimension, which is the one worth working on.
Calls we would still defend
Five separate scores, no composite — market viability, innovation, feasibility, monetisation and defensibility are graded on their own, so a strong idea with one weak leg reads differently from a mediocre idea across the board.
Revenue models as part of the result — each comes back with pros, cons and an effectiveness rating, because the second question after "is this good" is always "how would it make money".
Plain-language input — the founder writes a paragraph rather than filling a canvas, which keeps the friction low enough that an idea gets tested on the day it occurs to someone.
Built with
Next.js + React
Carries the three-step flow with results streamed as they are produced, so the wait is visible rather than a spinner.
LLM Analysis Engine
Reads a free-text description and returns structured per-dimension scores, which is the part a form-based tool cannot do.
Scoring Model
Holds the weighting across the five criteria, so the same idea described twice lands in roughly the same place.
Where it landed
What the build changed
5
Dimensions scored
market viability, innovation, feasibility, monetisation and defensibility, each weighted
0–100
Score per dimension
graded separately, never folded into one number
3
Steps to a result
describe the idea, wait for the model, read the scores
FAQ
The questions this build raises
What was actually built, the constraints it had to meet, and how it holds up in use.
You describe it in plain language and a language model grades it across five weighted criteria, including market viability, innovation and feasibility. Each comes back with its own 0–100 score rather than being folded into a single number, which is the point: the useful information is which dimension is weak.
Yes. Alongside the scores it proposes revenue models, each with its pros, its cons and a rating of how well it would work for that particular idea. That is the part that turns a score into a decision about what to do next.
You sign up, but you do not pay. It is free to use and there is no card, and the analysis comes back on the same screen rather than by email.
Keep looking
Other builds, taken apart the same way
automation
OutreachKits
B2B Sales & Lead Generation
fintech
TraderOps
FinTech & Algorithmic Trading